Live at a metropolitan municipality's 153 hotline
AI that listens to every contact-center call, scores it on the customer's own quality form, and ties each answer to the moment in the call.
audico.ai
The blind spot
Supervisors coach from the few calls they happened to hear.
Agents dispute a score that comes without the recording.
A dropped transfer or a wrong answer rarely reaches a report.
Volume from the hotline's signed technical specification (~1,400 calls/day). Assumes ~7 h of net listening per specialist per day.
The solution
153 → archive · daily pull
CONNECT
Recordings arrive from the phone system by daily pull, ZIP, CSV or API. The extension identifies the agent.
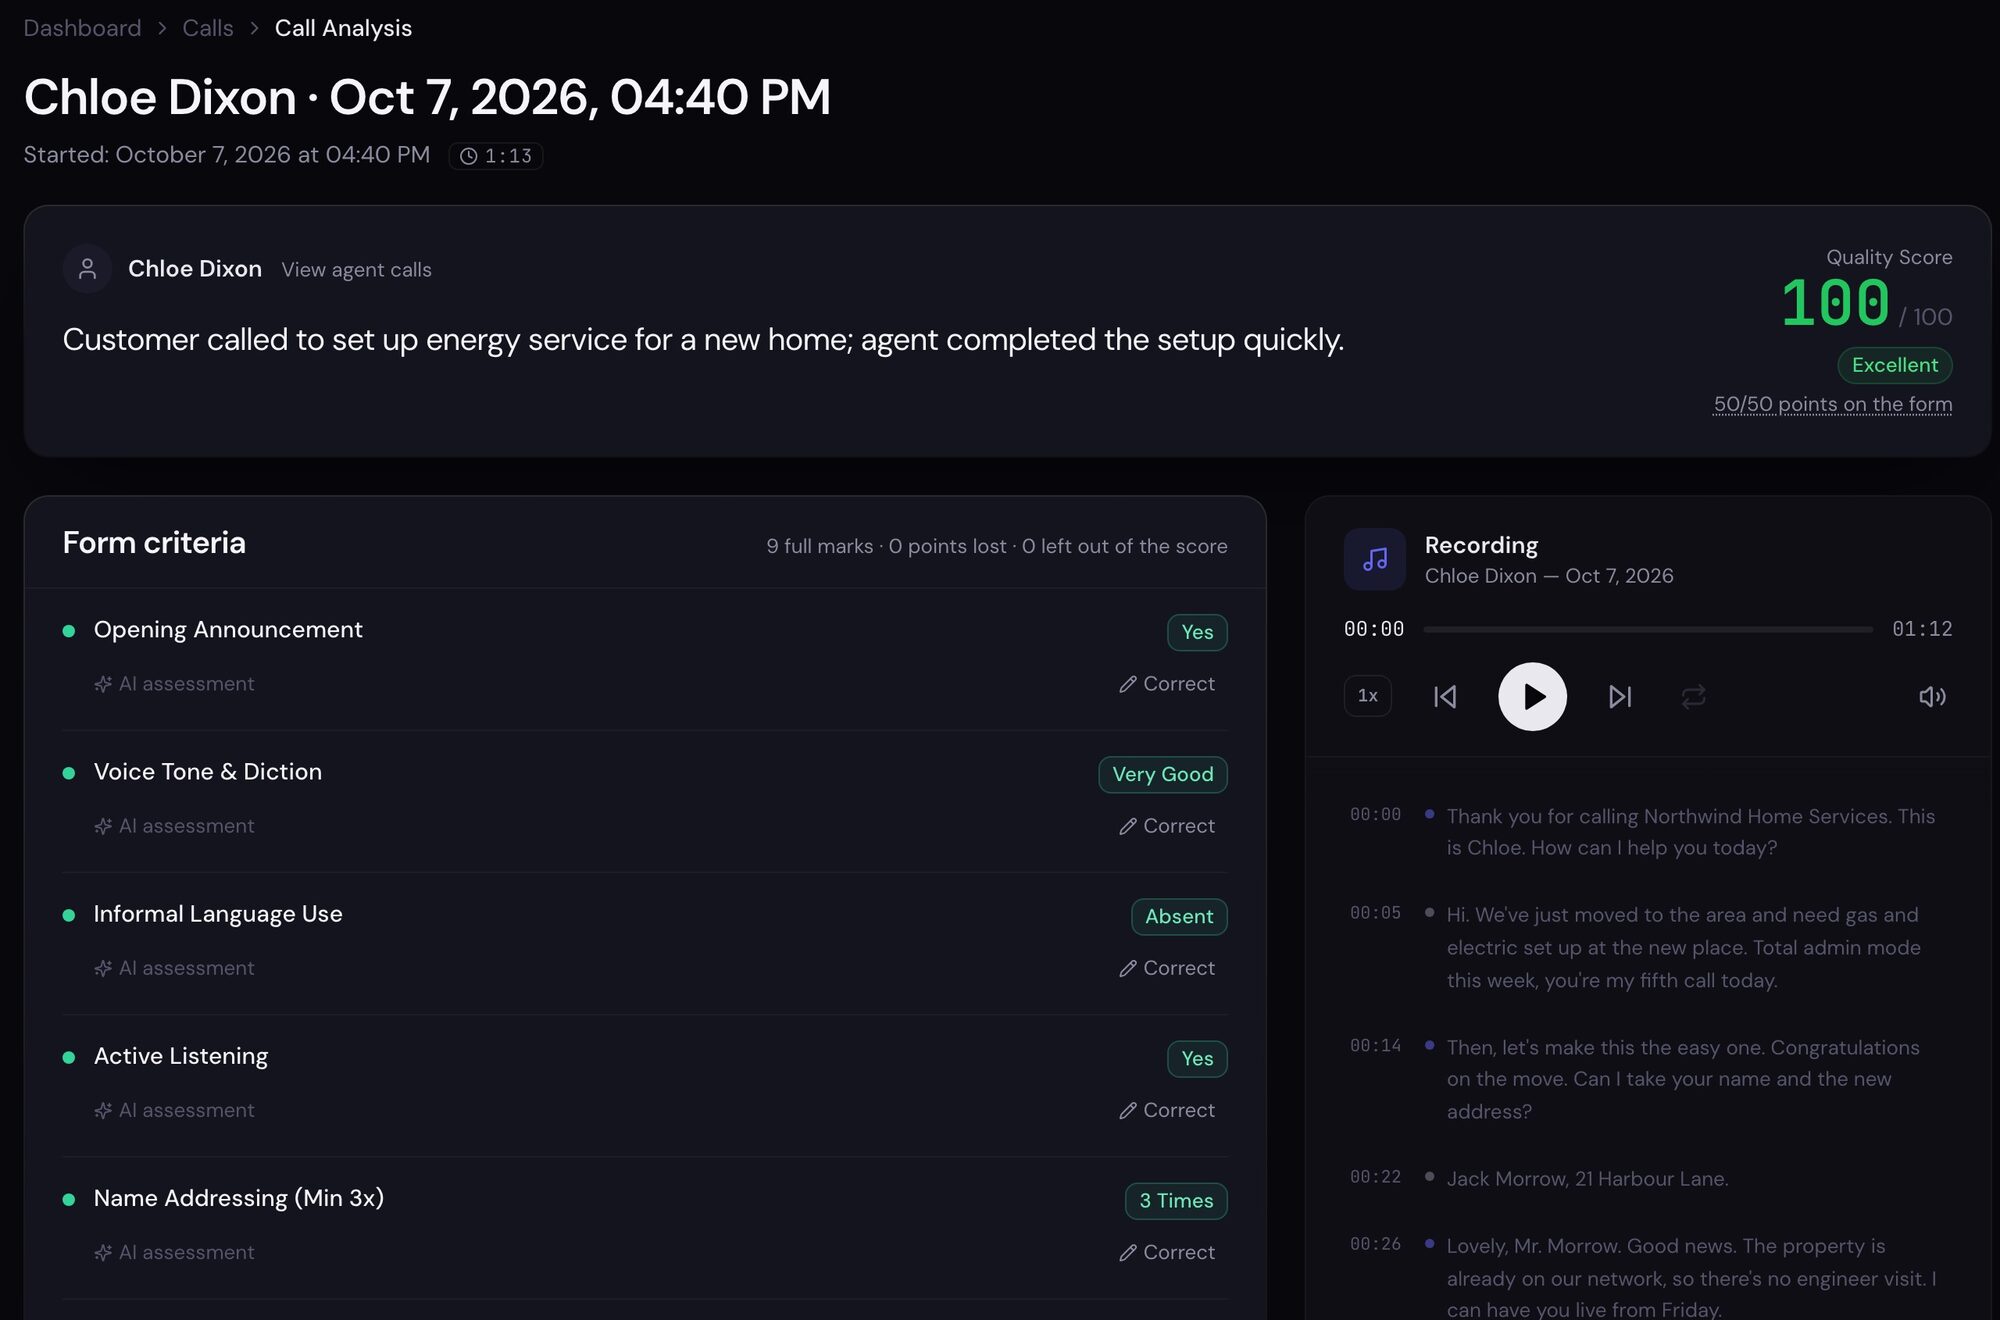
✓ Opening announcement 0:04
SCORE
Every call is transcribed and scored on the customer's own form. Each answer is tied to its moment in the call.
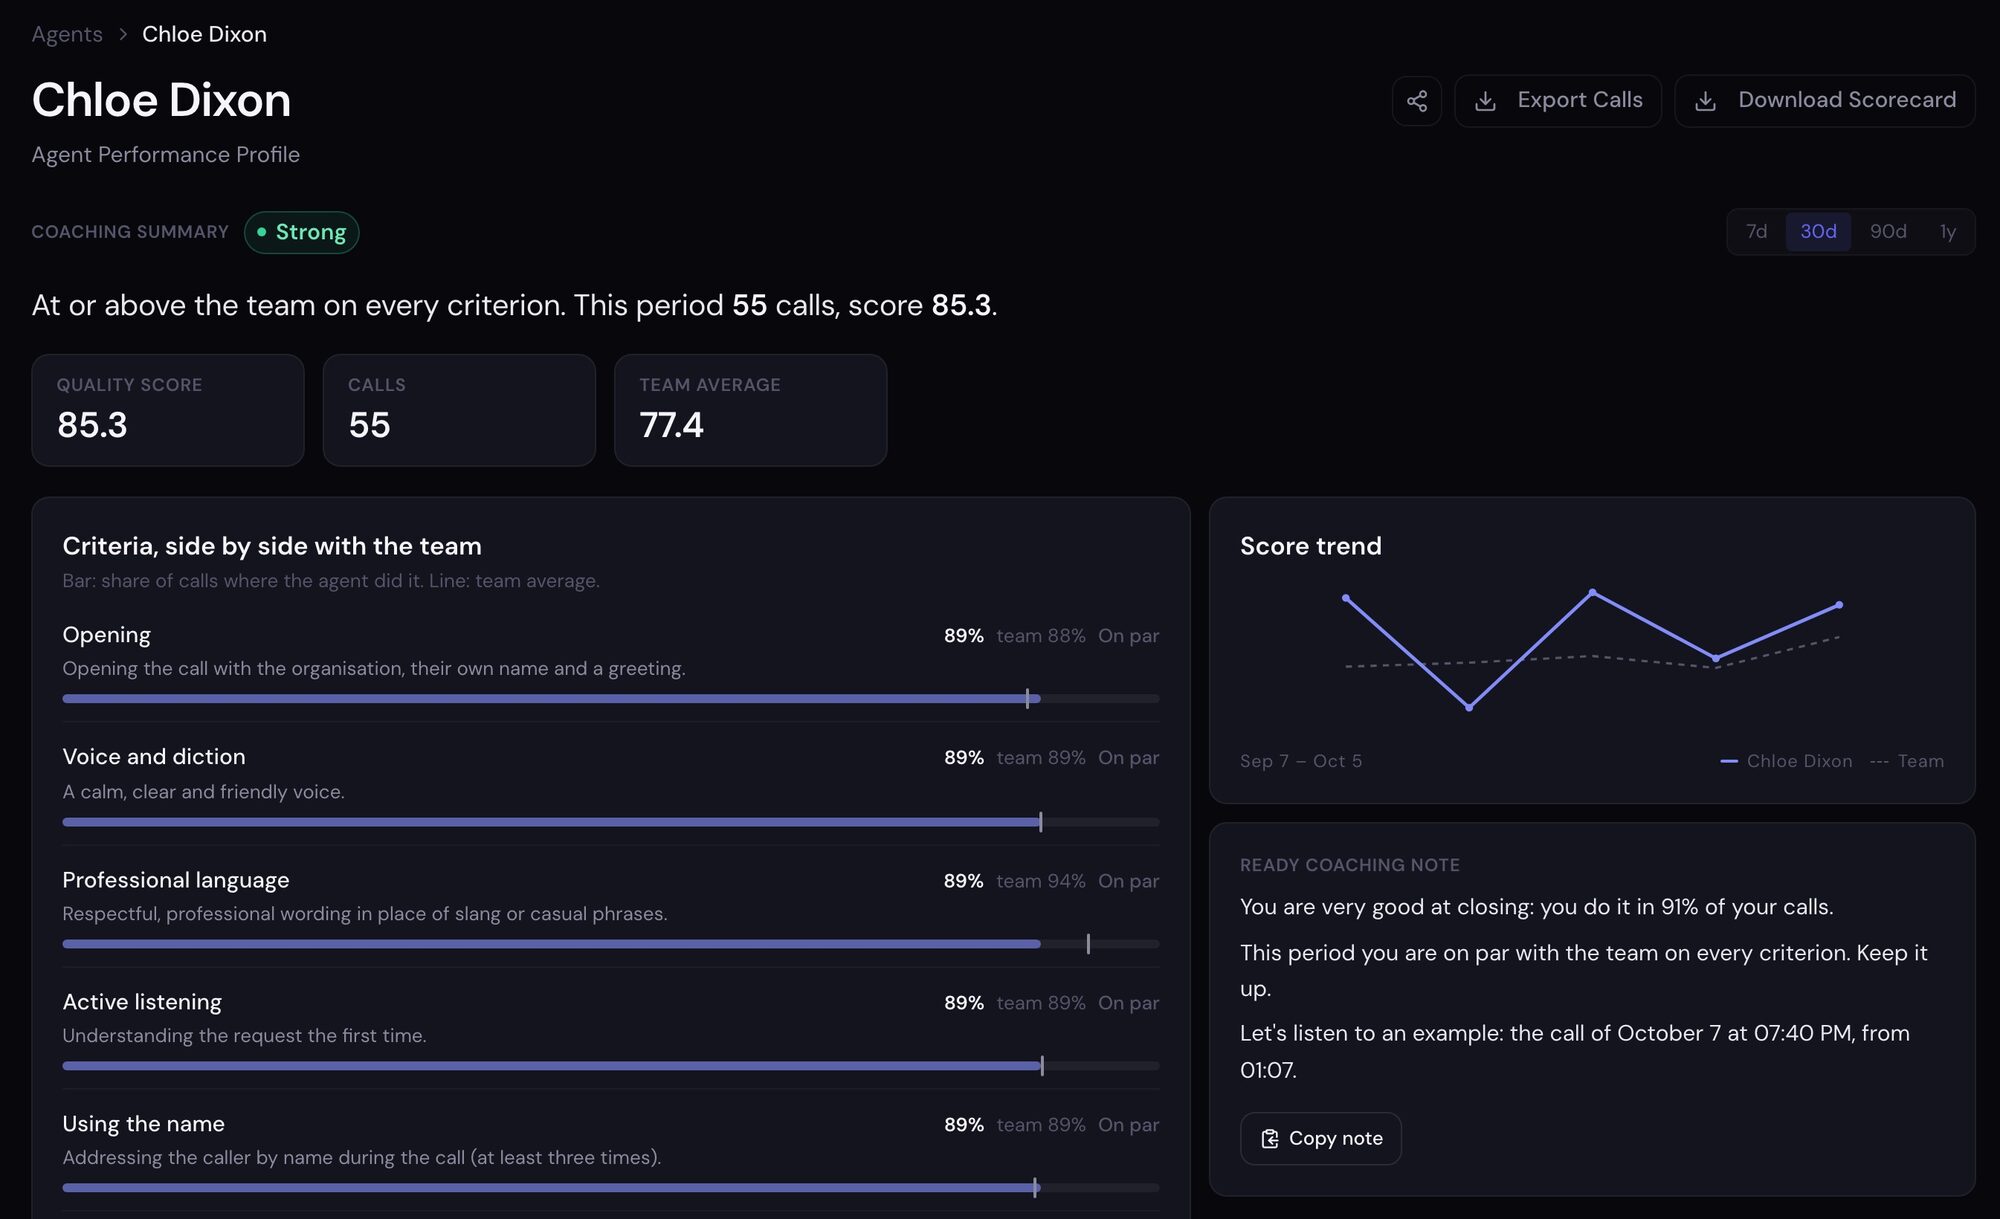
Coaching note · listen from 01:07
ACT
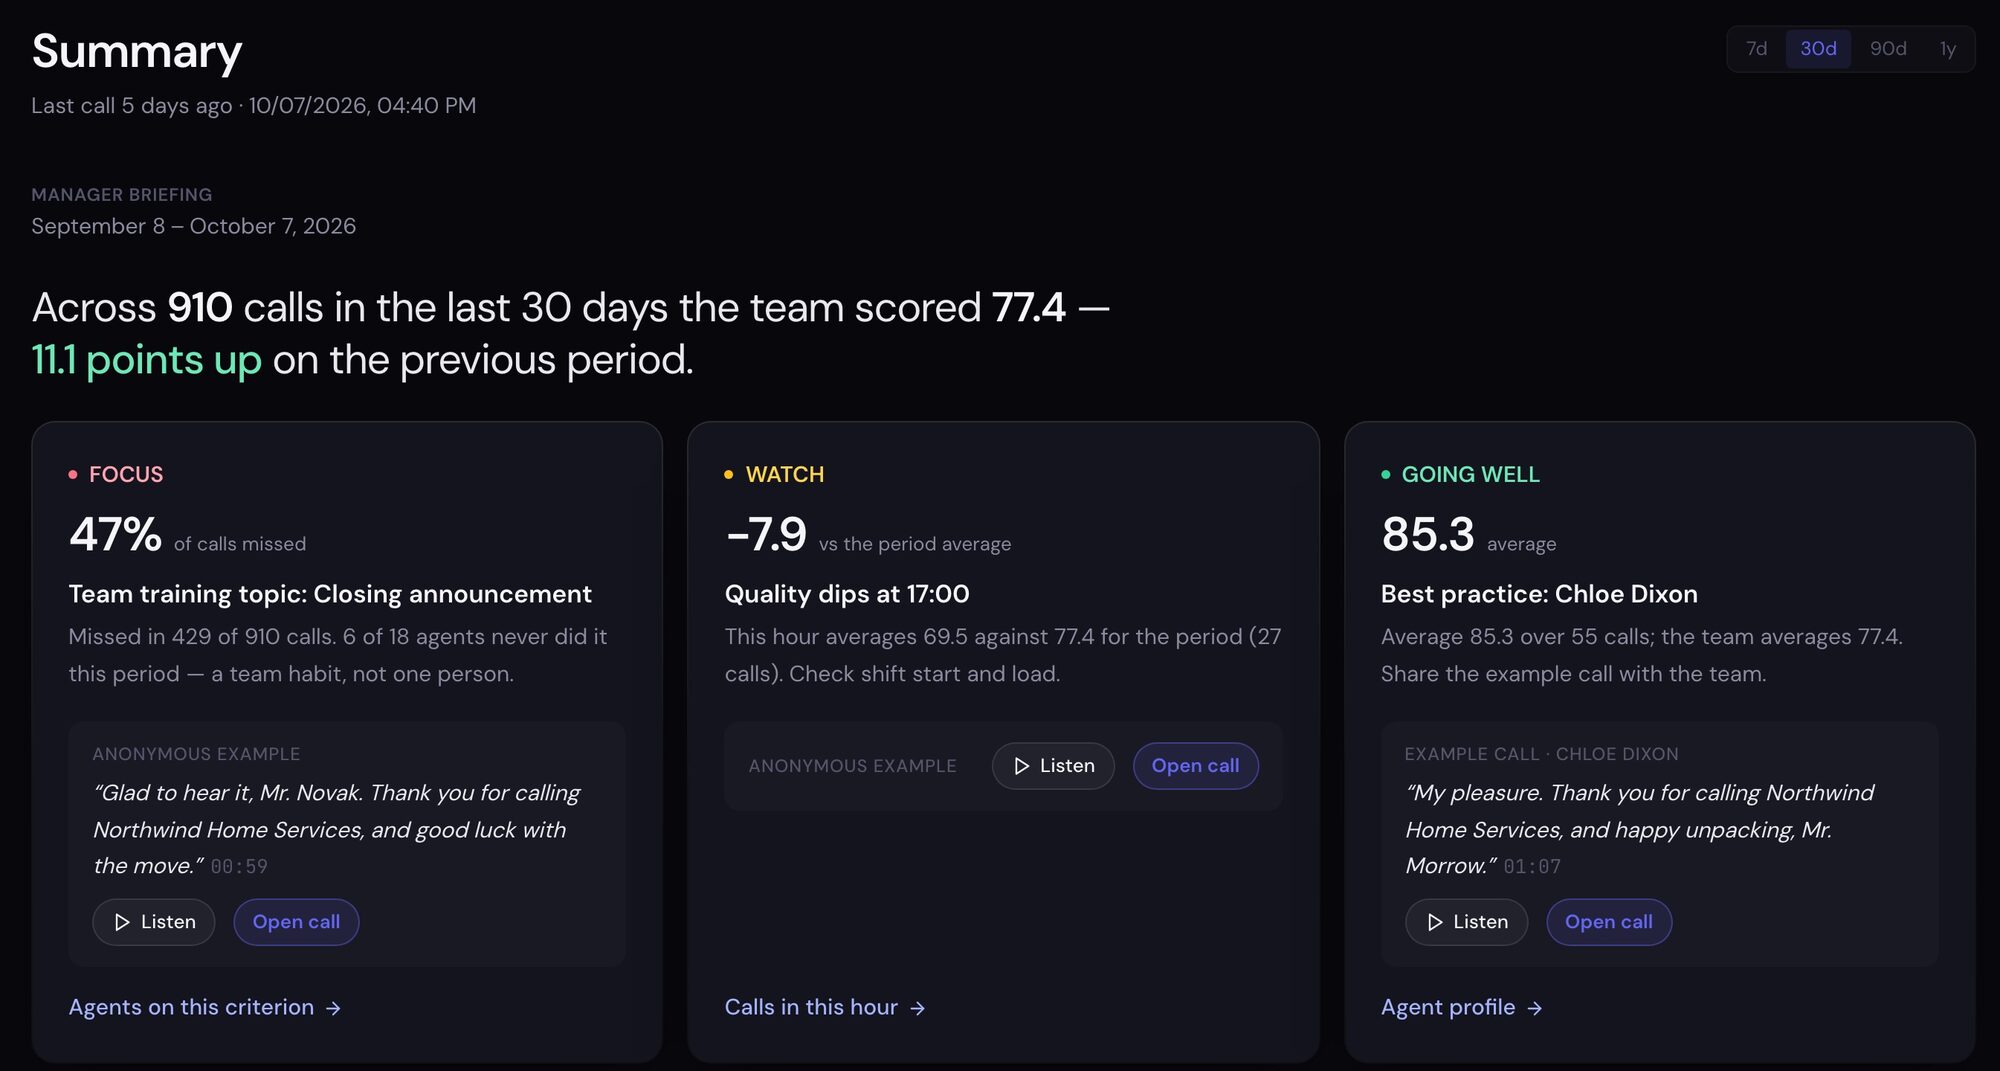
Coaching notes for every agent, a manager briefing, and AIRA, an analyst managers can simply message.
Watch it work
A simulated citizen call. Each criterion lights up at the second it is met, with the timestamp as evidence. The score lands when the call ends.
Simulated recording with AI voices. The same flow runs on every real call at the hotline.
Our edge
The left lane is this recording's real transcript. It shows the words, never the 77 seconds the caller spent waiting.
silent hold
from 0:25 to 1:42
The left lane is this recording transcribed by Whisper large-v3 turbo, uncorrected (shortened). It heard both “hello?”s but stamped them at 0:30 and 1:00, spread across the silence, and put the agent's return at 1:30. Red: a wrong time.
Scoring

Product screen · demo tenant, synthetic calls
How good is it
Agreement with the human QA specialist
Five audio criteria · 35 held-out calls
Same call, scored twice
Krippendorff's α across criteria on repeated runs
False factual claims in published analyses
1,742 claims audited in 974 calls
Tone and informal speech
Too weak to publish, so left blank when unsure. Main R&D target.
The 93% sample is small; a blind re-score by the QA specialist on a larger set is planned. We publish the weak criteria next to the strong ones on purpose.

Product screen · demo tenant, synthetic calls
Coaching
AIRA · the AI analyst
AIRA1,114 call contextWhich three agents need coaching most this month, and on what? Give me one example call for each.
The three agents who need coaching most this month are Sophie Turner, Olivia Bennett and David Park. The team averages 75.3; all three sit well below it.
| Agent | Calls | Score |
|---|---|---|
| Sophie Turner | 26 | 41.3 |
| Olivia Bennett | 143 | 67.3 |
| David Park | 26 | 67.5 |
Sophie Turner: opening and active listening met on only 53.8% of her calls (team 87.7%). Example: Sophie Turner · 10/3/2026, where the caller was sent to the website instead of the request being logged.
AIRA's answer, shortened · demo tenant, synthetic calls
Traction
MAR 2026
First use at Trabzon Metropolitan Municipality's 153 hotline; calibration with its QA specialist.
AUG 2026
Written with the institution: 99.5% availability SLA, data-protection terms.
23 SEP 2026
Paid license, public-sector procurement.
30 SEP 2026
Hosted in Istanbul, fed by an automated daily pull.
EARLY 2027
The offer provides for 12-month renewal.
calls a day, scored with no manual step
agents, each with a profile and score history
Türkiye's GDPR counterpart · in-country hosting · no training on customer data · one tenant per institution
Competition
| Capability | Global platformsObserve.AI · CallMiner · NICE | Custom projectAgency or in-house build | Audico |
|---|---|---|---|
| Scores the form by listening to the call, not from a transcript | Transcript first | Varies | ✓ |
| Local-language phone audio (8 kHz) | Partial | Varies | ✓ |
| The customer's own QA form | Partial | Varies | ✓ |
| Evidence for every answer | — | — | ✓ |
| Blank when unsure | — | — | ✓ |
| AI analyst for managers | Emerging | — | ✓ |
| What they actually sell | Search & dashboards | Consulting hours | Scored evidence |
Based on public information about each vendor category; individual products may differ.
Next market
metropolitan municipality in production
Scored on the institution's own form, hosted in Türkiye under KVKK.
calls accepted in 2023
By the service centres of the 115 network, run by municipalities and states. Same need: a score for every call, not a sample.
ready for high-risk rules
Systems that evaluate workers are high-risk (Annex III). Ours ships evidence per answer, human override and blank-when-unsure. GDPR: call data stays in the EU, never trains a model, one tenant per institution.
115 figures: Steuerungsbericht 2023 (115.de). A first German pilot is a goal for this round, not a signed agreement.
Seed round
A speech/ML engineer, customer success and public-sector sales.
From one reference to five institutions on one codebase, plus certification and in-country infrastructure.
Local presence, a GDPR review with a German DPO, a German phone-audio benchmark, and a first 115 service-centre pilot.
Contact-center QA software: $2.25B in 2025, about $4.1B by 2032 (Coherent Market Insights). Round size and terms in conversation.